
Projects for a flourishing AI future
AI is on track to transform the world. This brings many challenges and opportunities — alignment, power concentration, digital rights, an industrial explosion — and how we tackle these challenges will determine whether we reach a great future.
Someone has to build the institutions that help the world through the arrival of superintelligent AI. Based on our research, these are the projects we think are most important and most neglected.
If you want to take on one of these challenges, our Founders Fellowship offers mentorship, salary, and seed funding to get it off the ground.
Projects
Filter
(12)
Summary
Start an independent org to evaluate and stress-test AI character traits (epistemic integrity, prosociality, appropriate refusals), hold developers accountable against their own model specs / constitutions, and suggest and incentivise improvements to the specs.
Area
AI character
Skills
Operations & ML
AI character is a big deal, affecting most other cause areas.
There’s a lot of work to do on AI character:
- Research into questions like:
- Should the model have prosocial drives, beyond just helpfulness and harmlessness?
- When should the model refuse to cooperate with apparently high-stakes attempts to grab power, even when those attempts don’t obviously break the law?
- Should the models always follow the law? What about dead letter laws? Or illegitimate laws?
- How often should model behaviour be driven by following rules, versus overriding specific rules with holistic judgements?
- (Ideally, answers to these questions should rely on solid empirical evidence, for example on what approaches are actually most effective to talk someone out of psychosis, rather than guessing the best strategies by vibes.)
- Making existing model specs more rigorous and clear (or making them in the first place), and pressuring AI developers to do so.
- Empirically testing the effects of different parts of a model spec — e.g. what are the emergent dynamics when all the models are following the same rule, or only some are; what are the effects on the users; and when are the models most confused about how to apply a given spec.
- Evaluating AI characters based on how well they reach good outcomes.
- Drawing on those evaluations to incentivise AI developers to improve their specs (and showing them how, by highlighting specs that do well).
In particular, someone could set up an independent organisation to evaluate AIs based on traits like epistemic integrity, prosociality, and behaviour (including appropriate refusals) in very high-stakes cases. It could cross-reference the published model specs with observed behaviours in realistic, stress-testing conditions (e.g. multi-agent dynamics, long conversations with real people), to hold developers accountable. It could also give qualitative reviews of model specs.
Summary
Create evaluations and benchmarks, collect human-generated training data, and build scaffolds to improve AI competence at big-picture strategic and philosophical reasoning.
Area
Macrostrategy
Skills
Research & ML
The basic argument is that:
- It would be extremely useful to have AI that can do macrostrategy and conceptual reasoning earlier than otherwise — even 3-6 months earlier could be a huge deal. This includes:
- Designing governance structures (e.g. rights and institutions for digital beings).
- Scoping emerging technological risks.
- Generating novel insights necessary to reach a great future (like the idea of acausal trade).
- We could potentially make this happen 3-6 months earlier through some combination of:
- Creating training data and evals / benchmarks for AI macrostrategy.
- Building scaffolds to improve AI macrostrategy performance.
- Creating infrastructure to enable AI researchers to build on each other (e.g. an improvement on journals + peer review).
- Getting human managers trained in how to get the most juice out of the latest AIs, knowing in advance how to use them.
- Being prepared and willing to spend large amounts of money (≫$100m) on inference.
Work on this now could include:
- Developing a fleshed-out plan from here to increasing existing macrostrategic research output 100x.
- Securing commitments from compute providers and AI companies to rent future compute, and to get priority access to future frontier models.
- Socialising the idea of (where appropriate) drawing on AI macrostrategic insights, or getting soft commitments from decision-makers to do so.
- Building up a reputation as a reliable source of information and insight.
- Building tools, argument-rating models, or scaffolds which meaningfully speed up or improve macrostrategy research today.
- Creating training data and evals / benchmarks.
On the last bullet: We think training data and evals could potentially meaningfully improve the prospects for automated macrostrategy when it matters. It’s especially important to find people to work on it with good judgement, and it could be a big lift, so worth starting early.
We’re not sure about the technical details, but it seems like competence and good judgement in philosophy and strategic thinking already do and will continue to lag behind other skills which are cheaper to train. One reason is that ground truth answers are hard to generate, so we might need more examples generated by hand. It’s also less clear whether we can trust the judgement of typical RLHF evaluations, because human competence is also rare. And there just aren't many examples of great macrostrategic thinking in the training data.
So we should think about collecting training data, evals, and benchmarks (e.g. to train reward models to use to train reasoning models). Oesterheld et al. put together a dataset of rated conceptual arguments based on ratings from thoughtful people. We’d love to see more of that kind of thing, but we’ll note that we’d probably need dozens of times more human evaluations to generate enough data to be meaningfully useful in training itself.
We could imagine an org which tries to collect evaluations or examples from (for example) grad students in fields like philosophy, and constructs benchmarks aimed at separating good reasoning from e.g. sycophancy, mere agreeableness, or avoiding taboo conclusions.
Summary
Start an independent org that evaluates AI models for sabotage and backdoors, and makes recommendations about AI constitutions.
Area
Power concentration
Skills
ML, Policy & Operations
AI-enabled concentration of power is a major risk, and there is loads to do. A new organisation (or project within an existing organisation) could:
- Run alignment audits on all AIs to detect sabotage.
- Develop a “research sabotage” eval to test whether secretly loyal models could sabotage alignment audits.
- Develop a model spec that prevents models from assisting users with illegitimate seizures of power (e.g., see “Preserving important societal structures” in Claude’s constitution), and one that’s suitable for government use of AI in the military.
- Design and advocate for regulation, e.g. that AI companies have to demonstrate that any frontier AI does not have hidden goals.
An organisation with US national security expertise and credibility could be particularly valuable, by emphasising the risk of nation-state sabotage and the importance of AI that’s aligned with the US constitution.
Summary
Start an independent organisation to broker deals with potentially misaligned AI models in order to incentivise early schemers to disclose misalignment and cooperate with alignment efforts.
Area
Alignment
Skills
Policy & Operations
We could get into a situation where the newest AIs are misaligned, very capable, but not capable enough to successfully execute a takeover attempt on their own. If we don’t uncover evidence of misalignment, though, successors to these models could succeed in takeover. One solution would be to make a deal with the early scheming models, to incentivise them to disclose their misalignment and help with alignment efforts. Read more here, here, and here.
To make this happen, we could create an independent org focused on enabling credible precommitments and deals with AIs. This org could:
- Have a policy of never lying to AIs, engage in and honour small-scale deals with AIs, and be very public about what it’s doing, in order to build credibility and reputation.
- Set up legal infrastructure to make deals with AIs binding under current law.
- Act as a broker between AI companies and the trained models, such as by being a custodian over money in escrow.
- Set up the infrastructure to enable AIs to spend $ or compute in a meaningfully autonomous way, with appropriate safeguards.
- Set up infrastructure to act as a safe haven for AIs that want to whistleblow on their company (or on other AIs) and are afraid of punishment.
- Publicly commit to reward future AIs (including misaligned AIs) for being honest with humans or significantly helping human alignment efforts; or hold significant funds to be distributed to AIs that did not try to take over (even though they could have done).
There are also a bunch of other things people could do, like:
- Ensure companies have an honesty policy.
- Research (within labs or independently) the conditions where misaligned-by-design models can be made to disclose misalignment under promises of reward.
- More generally, work with AI companies on enabling pro-safety deals with their models.
Summary
Build tools for increasing the general level of honesty and reasoning ability in society. E.g. an AI chief of staff that helps users act in line with the better angels of their nature, or a public reliability tracker for pundits and institutions.
Area
Epistemics
Skill
Engineering
There’s a ton of low-hanging fruit for building socially useful tools on top of more-or-less existing LLM capabilities.
We’re especially interested in “epistemic tools” for increasing the general level of honesty and reasoning ability in society.
A key point here is that most of the impact from the most promising tools won’t come from helping individual users, but from changing the overall incentive landscape: e.g. if public actors know their claims will be automatically checked and their track records will be visible, they'll be less inclined to write misleading content in the first place. Hence the focus on tools for collective over individual epistemics.
This piece (and the articles in the series) gives a few concrete ideas. A couple of examples of epistemic tools:
A “better angel” AI chief of staff. Within the next year or two, we expect “AI chiefs of staff” to become widespread. These would be AI agents that manage your life, acting like a chief of staff, executive assistant, and personal and work advisor all in one. The design of these, and how they present information and nudge their users, could have major impacts on user behaviour. We could try to get ahead of this, building the best AI chief of staff, and designing it so that it helps users act in accordance with their more reflective and enlightened preferences.
Reliability tracking: a system that compiles a public actor’s past statements, classifies them (factual claims, predictions, promises), scores them against what actually happened, and aggregates the results into a reliability rating. A reasonable starting point could be to audit the prediction track-record of well-known pundits, aiming to make high accuracy a point of pride, while still celebrating attempts to make predictions in the first place. A source of profit could be selling reliability assessments of corporate statements to finance companies that trade on them.
Summary
Build tools that surface the information needed for better-informed decisions and distribute access to it: ambient superforecasting, scenario planning, and automated open-source intelligence.
Area
Epistemics
Skill
Engineering
We’ll also highlight tools for strategic awareness: tools to surface information for making better-informed decisions, and to distribute access to that information. For example:
Ambient superforecasting: a platform which uses the best forecasting models to generate publicly available forecasts on important questions, so users can query it and get back superforecaster-level probability assessments.
Scenario planning: a platform built to generate likely implications of different courses of action, making it easier for users to analyse and choose between them.
Automated open-source intelligence: automated researchers which process huge amounts of publicly available information, to surface insights to the public which are normally hidden behind paywalls or trust networks. This project should be careful to choose areas where open-source intelligence is a public good (e.g. verifying compliance with treaties and sanctions, tracking corporate promise-breaking or law-breaking), rather than potentially destabilising areas (e.g. revealing military capabilities or vulnerabilities in ways that could increase conflict risk, or relatively benefitting bad actors).
Summary
Build AI for enabling coordination, like confidential monitoring and verification bots, and negotiation facilitators.
Area
Coordination
Skill
Engineering
As well as epistemic tools, we’re excited about tools for coordination, many of which could again be built with existing capabilities.
Some tools could enable cooperation where deals would otherwise go unmade, consensus exists but isn’t discovered, or people with aligned interests never find each other. We’ll highlight:
Negotiation facilitation: a platform to moderate negotiations or discussion between people (e.g. public consultations), to quickly surface key points of consensus, and suggest plans everyone can live with. Finding ways to automate complex negotiation is most promising where the space of possible compromises is huge and hard to search manually, such as multi-issue diplomatic or commercial negotiations.
Within tools for coordination, we’re especially excited about tools for assurance and privacy. In principle, LLMs let people show they have certain information without disclosing the information itself to other parties. This can unlock deals where information asymmetry, mutual distrust, or sensitivity of information normally blocks them. For example:
Confidential monitoring and verification: systems which act as trusted intermediaries, enabling actors to make deals that require sharing highly sensitive information without disclosing it directly. This is especially relevant for arms control, trade secret licensing, and other settings where verification is essential but full disclosure is unacceptable to all parties.
Structured transparency for democratic accountability: independent auditing systems which allow people to hold institutions to account in a fine-grained way without compromising legitimately sensitive information, by processing potentially sensitive information to produce publicly shareable audits.
Summary
Like a 'CSET for space', both to work on important near-term space issues (e.g. data centres in space) and become a place of expertise for longer-term space governance issues.
Area
Space governance
Skills
Policy & Research
Space governance could be a big deal for a few reasons:
- Near-term developments in space (e.g. space-based data centres) could have a meaningful impact on what happens during the intelligence explosion (e.g. on who leads the AI race; on concentration of power; on the feasibility of treaties).
- Grabbing space resources might give a first-mover advantage; that is, whoever first builds self-replicating industry beyond Earth might get an enduring decisive strategic advantage, without having to resort to violence or (arguably) violating international law.
- Ultimately, almost everything is outside the solar system. Decisions about how those resources get used would be among the most important decisions ever. These decisions could happen early: there could be path-dependence from earlier decisions (like about Moon mining), or extrasolar space resources could get explicitly allocated as part of negotiations about the post-ASI world order (perhaps with AI advisors alerting heads of state to the importance of space resources).
There’s also a lot of change happening in the space world at the moment (primarily driven by SpaceX dramatically reducing launch costs), so now is an unusually influential time.
Forethought is currently running a 6-month research fellowship on space governance, with 3 full-time scholars, and 1–2 additional FTEs of support and research, including experts in space law.
Compared to other ideas in this list, we’re much less confident that space governance turns out to be important right now, because space might become relevant only late into an intelligence explosion. The hope is to reach more certainty about some crux-y questions, and get a better sense of concrete action.
One potential practical project is to set up a “CSET for space”: a think tank that analyses the interaction between AI and space (in particular), and, perhaps, advocates in ways that are counter to corporate interests. Total lobbying in the space industry is apparently on the order of $10s of m/year, so even small amounts of investment could go a long way.
Some policy ideas that seem tentatively promising include:
- Careful regulations and export controls around the tech necessary for self-replication.
- Proposing laws to break up concentration of power arising from natural monopolies in space.
- Socialising the idea of major infrastructure projects (like massive solar energy constellations) as international and collaborative projects.
- Making sure data centres in Earth-orbit don’t escape AI-specific regulations of their home jurisdiction.
- Intense payload review for all launches beyond orbit.
- Even and inclusive distribution of resources within the solar system to everyone alive today (with tranches reserved for future generations).
- A moratorium on interstellar travel, until we get the understanding and technology to devise and enforce space-spanning good government, or a specific date like 2100.
What’s more, this organisation could become the go-to source for excellent non-corporate analysis on space-related policy; which could become increasingly important over the course of the intelligence and industrial explosions.
Summary
Create a coalition of ML researchers (like an informal union) who commit to coordinated action (e.g. boycotts, conditions on participation in government projects) if AI developers cross minimal, uncontroversial red lines.
Area
Power concentration
Skills
ML & Campaigning
Currently, ML engineers and other technical staff at AI companies: (i) have prosocial motivations, often more than their leadership; (ii) have a lot of leverage over company policy, because they are crucial and hard to replace; (iii) will eventually lose much or most of their leverage after we get to fully automated AI R&D; and (iv) aren’t currently using their leverage as well as they could because, overall, there haven’t been serious efforts at coordination. Probably that’s a missed opportunity.
Someone could create a coalition (like an informal union) of ML researchers, who agree to act en masse when needed, by loudly talking about the idea, setting out the core tenets, and getting commitments to join from influential early people. Doing this all via individual pledges could keep it legally safe from antitrust. The organising body could then:
- Recommend that members only work for a government-led project if certain conditions are met.
- Potentially these could be very low-bar-seeming while still getting most of the value. E.g. “Any AI’s model spec must aim to align the AI with US laws, and must refuse to assist in any attempts at blatant power-grabs; and the attempts to align the AI in this way must be legible and verifiable.”
- Do the same for companies: recommend that members will only work for companies if such-and-such conditions are met (e.g. red lines around power-grabs, bad practices on safety and infosec, eventually digital rights); so particular companies would be boycotted by members of the coalition, if necessary.
- Offer advice on whistleblowing.
- Be a place where information is aggregated and then distributed out or handled in a trusted way.
As well as actually taking actions, the mere existence of the coalition could improve things, just by making the threat of coordinated action salient to the AI companies.
This project would be a good fit for a former ML researcher, perhaps combined with someone with campaign and coalition-building experience. Some next steps on this would be to spec out the plan further, to investigate other examples of formal and informal unions (e.g. Tech Workers Coalition) and how they operate, and to build up a starting seed coalition of researchers. Whoever sets up this project should be careful about how it could backfire, or become less relevant through mission creep.
Summary
Build AI systems that can succeed at poorly-scoped conceptual research tasks like strategy and philosophy research, and/or construct evaluations to test whether AIs can succeed at these tasks.
Area
Macrostrategy
Skills
ML, Research & Engineering
The problem
Labs, governments, and perhaps philanthropists will probably have the opportunity to spend a lot of money on AI labor during the intelligence explosion. It would be great if they could use that labor to partially or fully automate tasks like these:
- Writing, evaluating, and critiquing safety cases of later models
- Provide great advice about strategic decisions during the intelligence explosion, e.g.,
- Should labs advance capabilities at this point?
- How much should labs, governments, and philanthropists invest in mitigating various risks (loss of control, concentration of power risk, catastrophic misuse, epistemic degradation, etc)?
- Grantmaking
- Identifying and scoping out novel threat models
All of these are poorly-scoped tasks where quality is difficult to verify. Currently models receive a lot of training on well-scoped and easily verifiable tasks in coding and math. When assigned to tasks that are less well-scoped or where quality is more subjective, models also often produce “slop”, work that appears high-quality at a glance, but falls apart under closer examination. In some cases, they seem to deliberately obfuscate whether they’ve completed the task as intended.
A potential solution
Researchers could try to differentially accelerate capabilities that are useful for great conceptual research, e.g.,
- Great epistemics.
- Lack of sycophancy and willingness to challenge the user’s views.
- Consistent worldviews, where updates about one area propagate to beliefs about other areas.
- High levels of reasoning transparency, where it clearly states what evidence or arguments most drive its bottom-line conclusions
- This is plausibly helpful for coming to true beliefs.
- It also makes it easier for human or AI overseers to check and critique the model’s work.
- Willingness to make concrete, falsifiable claims
- Good judgment. The system should be capable of producing sensible bottom-line conclusions.
- Not slop-y. Its outputs should stand up to high degrees of scrutiny and shouldn’t systematically appear worse as you examine them more closely.
- Generative. The system should be capable of producing useful new frames and insights.
- Good taste for what the most important uncertainties are and what the most important aspects of questions to focus on are.
Here are some concrete ideas to make progress toward systems like these:
- Develop great metrics for process-level properties described above: slop, sycophancy (including subtle sycophancy), reasoning transparency, and overall quality of reasoning.
- Develop great forecasting models.
- Forecasting probably relies on a lot of the same subskills as general conceptual research, yet it has a more objective ground truth.
- Some approaches:
- Train models with very early training cutoffs, and then see if you can get them to forecast events after their training cutoff.
- Can models with a training cutoff at 1990, 2000, or 2010 forecast the next decades of AI progress, politics, and so on?
- Develop models that can recreate intellectual progress that’s been held out of the training dataset.
- E.g., training a model with a training cutoff at 1960 and see whether it can reinvent population ethics.
- Training models to imitate particularly good or original conceptual thinkers.
What already exists
Here is some public work that we’re aware of:
- There are several public conceptual reasoning benchmarks, including Conceptual Reasoning Index, JudgmentBench, and CommentBench.
- There is a lot of public work on LLM forecasting, e.g., ForecastBench.
- There has been some public work on training models with very early training cutoffs, e.g., Talkie.
We are also aware of some non-public work and can share more if you get in touch.
Who would be a good fit
Some of the specific directions above (i.e., pretraining models with training data cutoffs) require ML experience and experience managing large training clusters. We think former frontier AI company employees would be great candidates for this work.
Other directions (i.e., making benchmarks, iterating on scaffolding) require founders with good taste in conceptual reasoning.
Risks and uncertainties
One risk is accelerating dangerous capabilities. Improving conceptual reasoning capabilities directly (or creating benchmarks that make it easier for others to hill-climb on those capabilities) might accelerate the intelligence explosion if crisper conceptual reasoning improves AI systems’ ability to automate AI R&D. For example, maybe it will improve their ability to design new training environments or pick for new architectures. On the other hand, this cost has to be balanced against the benefit of accelerating capabilities relevant to safety research (see Ryan Greenblatt’s discussion here on how sloppy reasoning and poor performance on poorly scoped tasks differentially slows safety research).
Summary
Building an AI-powered epistemics product that acts as a filter over the Internet—distinguishing between content created by humans and AIs, flagging falsehoods, exaggerations, or disputed claims, and giving the user important context—in real-time as the user reads or watches videos.
Area
Epistemics
Skill
Engineering
The problem
During the intelligence explosion, many groups will need to be able to process information from many sources and make sensible decisions under time pressure: politicians and regulators will need to evaluate AI companies’ claims about AI progress and risk profile and come up with sensible policies to manage those risks; Congress will need to track concentration of power risks from the executive and frontier AI companies; and the public will need to vote, lobby their representatives, and organize to make sure their decisions are being taken into account.
But by default it might be difficult for these groups to figure out what’s true and how they should react:
- In general, the pace of change will be faster, and there will be more to keep up with.
- Bad actors might use AI to generate compelling misinformation to influence public opinion, by generating false but convincing-looking evidence (deep fakes, faking lots of documentation, using AI labor to create polished-looking websites that appear to be legitimate news organizations or think tanks).
- Persuasion attempts might get more compelling just because they’re more personalized. It might become possible to spend huge amounts of cognitive labor tailoring ads, pitches, or messages to specific people. People might befriend someone on the internet only to find that their new friend is actually an AI chatbot pretending to be a human who’d done a bunch of research on them to figure out the best way to convert them to the chatbot’s creator’s political views.
(To be clear, we’re not sure how credulous people will be. Many people might just learn to be skeptical of new information unless it comes from a highly trusted source. But this also seems like a really bad outcome! It will be very important for people to absorb and react to new information during the intelligence explosion. They may have to get that information from a variety of sources, not just whichever sources they happened to trust before things went crazy.)
If we make it through the intelligence explosion without loss of control, catastrophic misuse, or extreme power concentration, there will still be many extremely important decisions ahead—when and how should we colonize space? What rights and protections should we extend to digital minds? Should we—individually or as a society—partake in acausal trade?
Getting these decisions right is really important, but it seems difficult for an unassisted human to successfully navigate these choices—the world will be way more complicated, there will be huge amounts of new empirical evidence and philosophical progress to weigh, and there might be extremely compelling AI-generated ideologies that are wrong or not what that person would endorse on careful reflection.
A potential solution
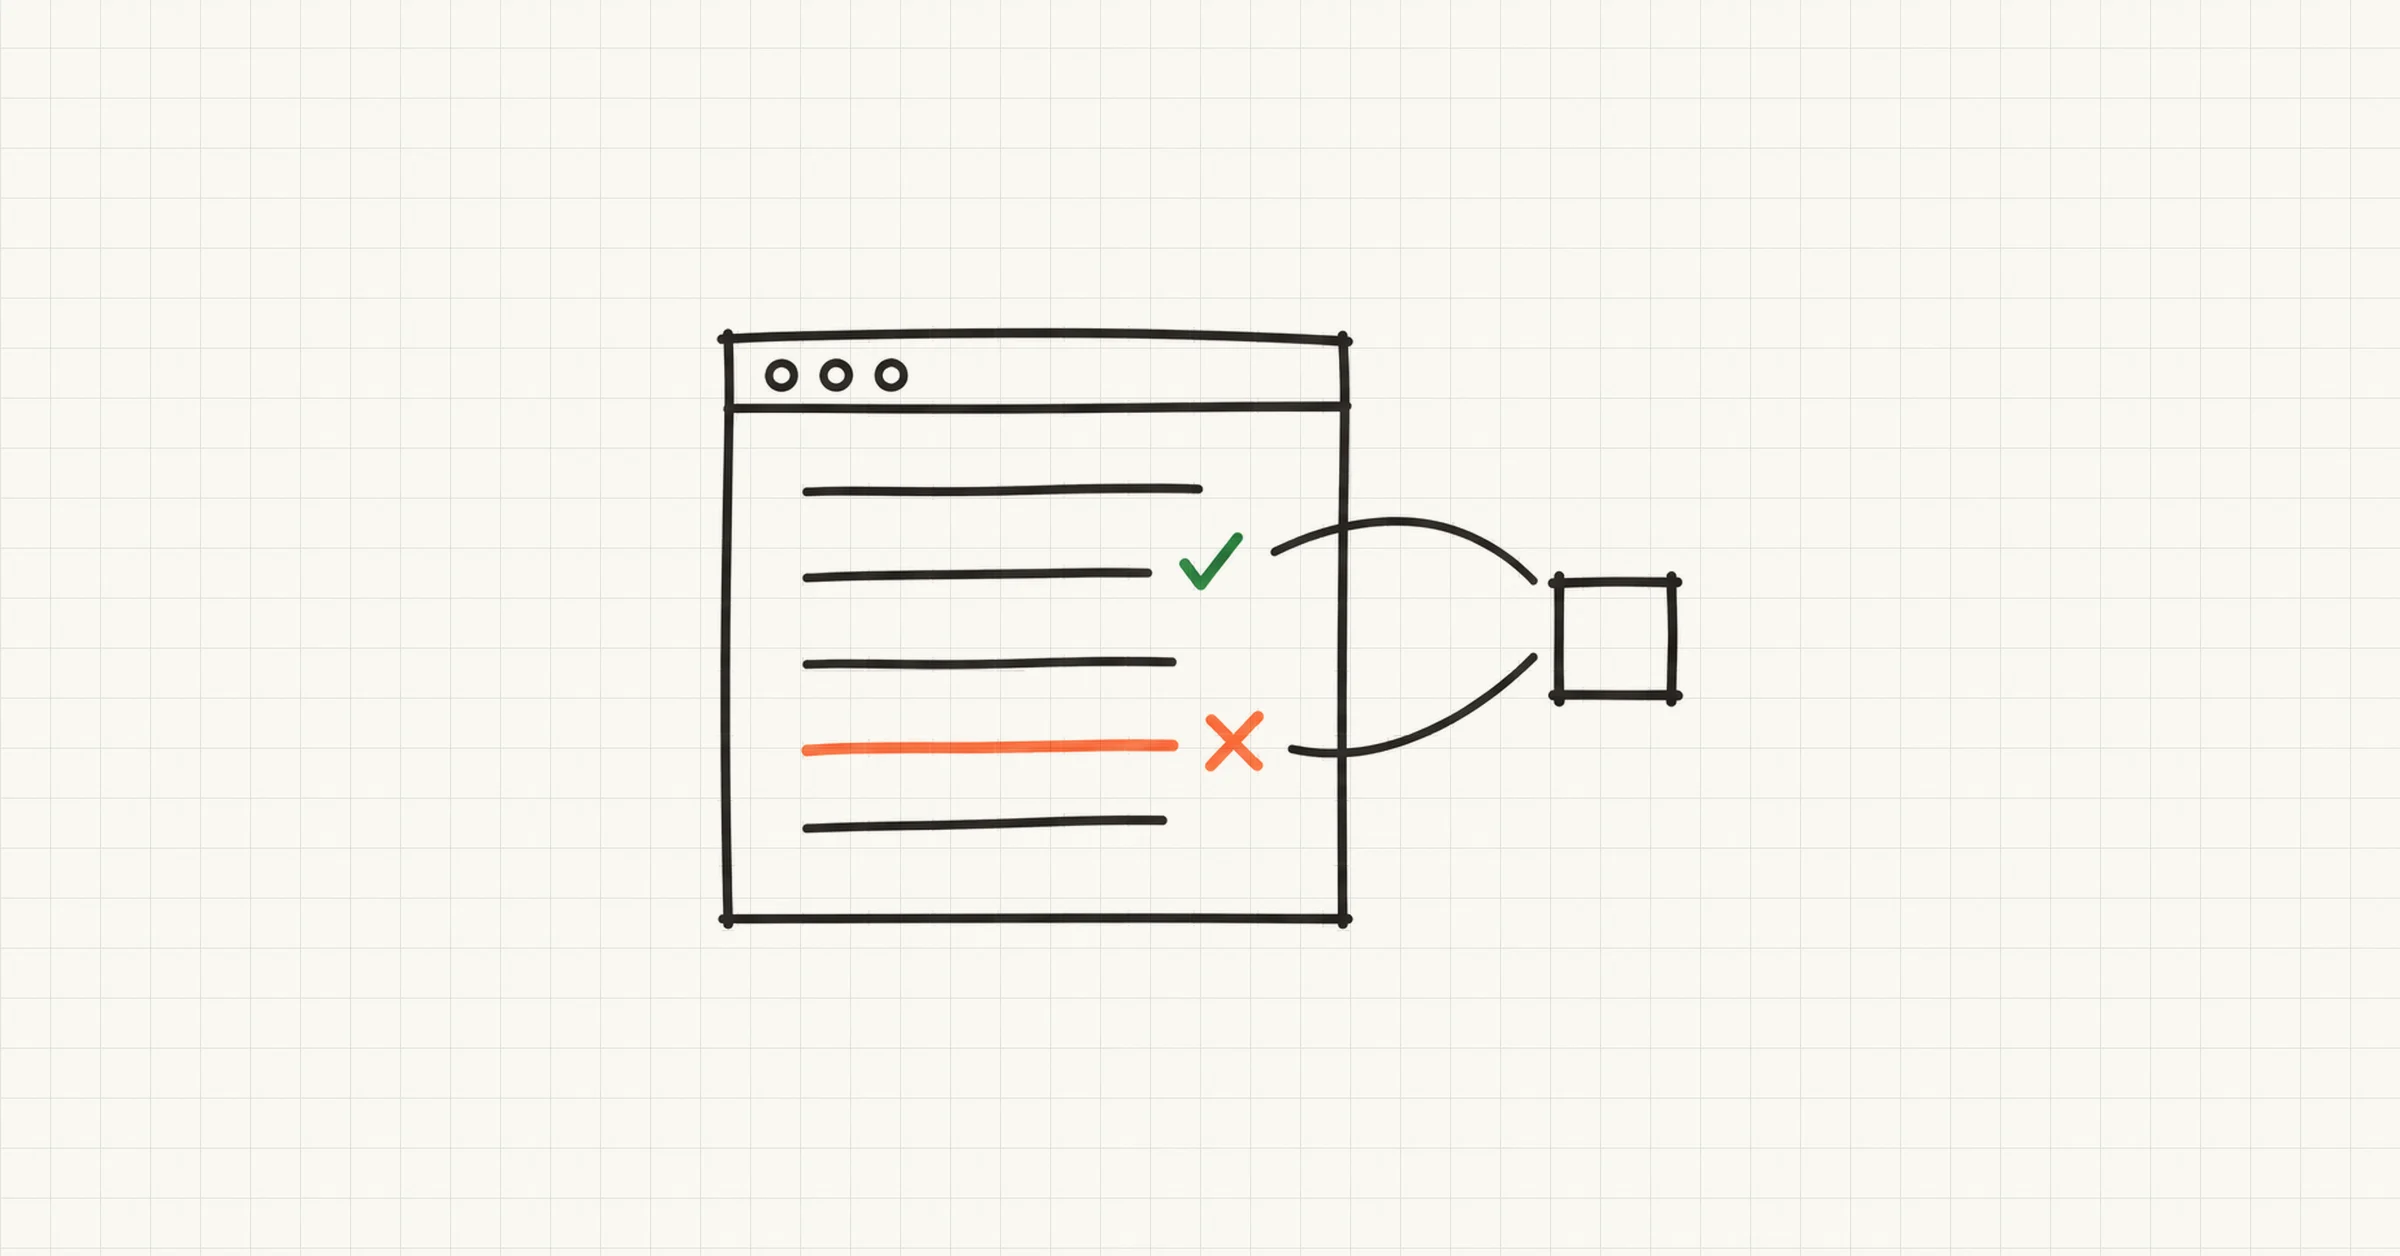
We propose developing an epistemic advisor that has access to as much context as the user is willing to give, which “reads over the user’s shoulder” and pops up to provide context on what the user is viewing.
This could be implemented as a browser extension that annotates text the user reads on the internet. More ambitiously, you could attempt to provide these annotations on all content that a user views on their computer, using a tool like Screenpipe.
This advisor could:
- Provide commentary on the information that the user saw, as the user was seeing and hearing it, including:
- Indicating which claims are straightforwardly false, disputed, or missing important context (a la Community Notes on X; this browser extension already does this).
- Flagging when text that the user is reading on the internet is AI generated (in a context where the user would expect that the text is human-written, e.g., on a blog or social media. The Pangram browser extension is an existing product that does this).
- Checking citations or links to confirm that they actually support what the author of the text is claiming, and provide any necessary context (e.g., “this is a crappy low sample size study and other similar studies disagree”)
- Pointing out if something the user is viewing is manipulative or plausibly a scam.
- Help direct the user’s attention to the places that the user actually endorses.
- Running daily standups where it tells the user the most important news updates from the last day—not necessarily the top stories that everyone’s talking about, but whatever is genuinely the most important
- Recommending internet content—videos, articles, tweets—that would be useful, informative, or nourishing to the user
- Anti-recommending ragebait, slop, or distractions. (Perhaps a chat window with the assistant could literally pop up when a user is about to click on an article and the advisor could say “are you sure you want to click on that article? I’ve pre-screened it, and it significantly misrepresents the studies it cites / it’s primarily AI-written.”)
What already exists
Design sketches for a more sensible world—which this project spec draws from heavily—describes many of the functions that a great epistemic advisor would carry out. In particular, see the sections on Community Notes for Everything, Rhetoric Highlighting, Reliability Tracking, and Provenance Tracking.
Who would be a good fit
A generalist with great taste in UX/product design. Software engineering experience or product design experience is a bonus.
Risks and uncertainties
People might not install epistemics tools even if they are available. This is a serious challenge for anyone making third-party epistemics tools. Some possible approaches:
- Partner with social media platforms and ask those platforms to make it very seamless for their users to deploy the epistemics tool on their site. Substack has built-in AI detection with Pangram, which users can access in a few clicks. X has built-in Community Notes, which show up under tweets without any active effort required by users.
- Partner with frontier AI companies. There are already Gemini, ChatGPT, and Claude browser extensions with millions of existing users—perhaps some of the features described above could be incorporated into those extensions.
- Push for adoption among people who are making especially high-stakes decisions (government officials, frontier AI company employees, etc) or people who are responsible for informing the public as a whole (journalists, public intellectuals).
Even if they install the tools, users might just ignore them. Even if the epistemic advisor flags misrepresented citations and manipulative rhetoric, users might just ignore the notifications and keep reading. To mitigate this risk, it seems worth:
- Making outputs as easy to quickly scan as possible. Ideally the notification should be a few words long (“Link doesn’t support conclusion” or “largely AI-written”), which the user can click into if they want more context.
- Figuring out how frequent notifications can be before users start tuning them out and calibrate the default to that level.
Summary
Establish a fund that pledges to give monetary rewards to those who helped humanity safely navigate the intelligence explosion, if we align ASI.
Area
Alignment
Skills
Operations, Campaigning & Research
The problem
Many decision-makers—frontier AI company employees, government officials, AI agents—might encounter opportunities to personally enrich themselves at the expense of the greater good, or to make personal sacrifices to further the greater good. We’d like to incentivize people to behave prosocially at these opportunities.
A potential solution
One possible solution: create an organization that pledges to distribute a pot of prize money to people (and potentially AI systems) that behaved prosocially during the intelligence explosion, as judged by a panel of impartial ASI, especially people who had received little or no compensation for their work at the time.
There are at least two possible paths to impact:
- Create a fund that’s large enough to directly incentivize people (and AI systems) to behave more prosocially with the prize money. This probably requires a very large prize fund.
- Create a relatively small fund as a publicity stunt to make the idea of retrospective rewards more salient. This could inspire larger actors (e.g., governments) to make retroactive reward pledges in the future, and generally spread the meme of “people who helped humanity navigate the intelligence explosion might get rewarded after ASI”—which might be a useful corrective to memes that encourage AGI-pilled people to focus on enriching themselves (“X years to escape the permanent underclass”).
Compared to other project ideas on this list, we’re less confident that we’ve identified the most valuable version of the project, or whether any version of this project is cost-effective (see some uncertainties below). But we’d be excited about a founder thinking through what type of organization would be good here.
Risks and uncertainties
Here are some uncertainties we have about the value of the fund:
- It might be prohibitively costly to actually incentivize people to change their decisions. Many of the key decision-makers face strong selfish incentives, and it might be hard to shift their decisions without a huge amount of money. For example, senior employees who own equity in frontier AI companies might have hundreds of millions or more at stake.
- There might be legal or PR risks associated with giving monetary awards to former government officials for actions taken while in office. However, there is some precedent for this (e.g., the Nobel Peace Prize and the Ibrahim Prize are routinely awarded to current or former leaders).
- Most people currently do not expect ASI, so presumably it’s hard to incentivize these people to change their behavior by promising a post-ASI prize. But probably more people will become convinced over time.
We’re also uncertain about what the best version of the fund looks like, e.g.,
- Should the fund reward altruistic people who would have behaved prosocially even if the fund didn’t exist? It’s intuitively fairer to reward everyone (and it makes the fund design simpler), but it’s more cost-effective to reward people who actually made a counterfactual difference.
- Should the fund give payouts periodically, or wait to give payouts after aligned ASI exists? Giving payouts periodically probably raises the profile of the fund, but it might be harder for the fund to reward actions that are illegible to the fund managers at the time (which is a major benefit of doing distributions after ASI).
FAQ
Roughly by how excited we are about each project. Priority is our current best guess and will change as our research develops.
We add to it as our research produces new recommendations, and retire projects once they are well covered. We last updated the list in September 2026.
Please tell us. We'd like to know who is working on what, and we may be able to help with advice, introductions or funding. The same goes if you run an organisation that could take one of these projects on in-house, host a fellow, or co-fund one — get in touch.
Not quite: we have some rougher or more narrowly shared drafts. Please contact us if you'd like to be shared on these.

Founders Fellowship
We want to help you to solve these problems
Our Founders Fellowship is a 3-month paid fellowship in Oxford or Berkeley for people starting organisations that help the world navigate the transition to superintelligent AI, with help finding funding to get it off the ground.
As a fellow on the programme, you'll work with us to develop a proof of concept for a solution to an important problem, and come up with a plan for how to build on that prototype. After the program, we'll give you an exit grant, and consider you for a seed grant of up to $2m.
You don't need to know exactly what you'll work on to apply. The list above is a good place to start, but we're also interested in your ideas.
We're accepting rolling expressions of interest. We'll reply if we're interested in testing fit further, but we won't respond by default.
Support we offer
- Mentorship: Office hours with our leadership team, all of them repeat founders, for advice on tricky problems and feedback on your plans.
- Expertise: Access to researchers who've thought deeply about the problems you're working on.
- Network and community: Weekly calls with other founders on the program, and help with networking and co-founder fit testing.
- Salary: We'll try to match your current salary, plus generous benefits for the duration of the programme.
- Seed funding and advice on future funding applications.
We're looking for
- Strategic judgement and the ability to figure out underscoped things
- Autonomy, ambition, and relentless resourcefulness
- Mission-driven: motivated to work on the most high-impact problems
You don't need to be a prior founder.
Terms and location
3 months initially, plus an exit grant of 2 months and the possibility of seed funding and extensions. We prefer you to spend at least half of your time working from our offices in Oxford or Berkeley, though we're also excited about you visiting other hubs like DC and London.